Coming soon.
Mandi Zhao
I'm a Research Scientist at Meta Robotics Studio. I did my PhD at Stanford University advised by Prof. Shuran Song. My B.S. and M.S. are from UC Berkeley, where I worked with Prof. Pieter Abbeel at Berkeley AI Research (BAIR). I'm broadly interested in AI for robotics: data-driven approaches that enable embodied systems to perceive, reason, and act in the real world.
News
- Summer 2025Research intern at Meta FAIR - Menlo Park, CA.
- Summer 2024Research intern at NVIDIA Seattle Robotics Lab - Santa Clara, CA.
- Summer 2022Research intern at Meta FAIR - Pittsburgh, PA.
Research
International Conference on Machine Learning (ICML), 2026
DexMachina: Functional Retargeting for Bimanual Dexterous Manipulation
We study the problem of functional retargeting: learning dexterous manipulation policies to track object states from human hand-object demonstrations. We focus on long-horizon, bimanual tasks with articulated objects, which is challenging due to large action space, spatiotemporal discontinuities, and embodiment gap between human and robot hands. We propose DexMachina, a novel curriculum-based algorithm: the key idea is to use virtual object controllers with decaying strength: an object is first driven automatically towards its target states, such that the policy can gradually learn to take over under motion and contact guidance.
International Conference on Learning Representations (ICLR), 2025
Real2Code: Reconstruct Articulated Objects via Code Generation
We present a novel approach to reconstructing articulated objects via code generation. By leveraging pre-trained vision and language models, our approach scales elegantly with the number of articulated parts, and generalizes from synthetic training data to real world objects in unstructured environments.
International Journal of Robotics Research (IJRR), 2024
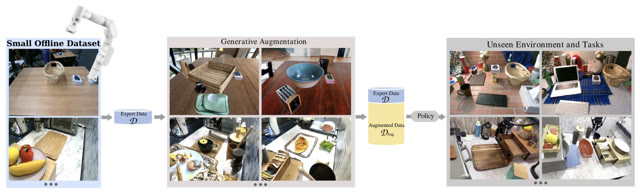
Semantically Controllable Augmentations for Generalizable Robot Learning
We posit that image-text generative models, which are pre-trained on large corpora of web-scraped data, can serve as such a data source. These generative models encompass a broad range of real-world scenarios beyond a robot's direct experience and can synthesize novel synthetic experiences that expose robotic agents to additional world priors aiding real-world generalization at no extra cost.
MD-Splatting: Learning Metric Deformation from 4D Gaussians in Highly Deformable Scenes
We achieve simultaneous 3D dense point tracking and dynamic novel view synthesis on highly deformable objects. Our method, MD-Splatting, builds on recent advances in Gaussian splatting and learns a deformation function to project a set of canonical Gaussians into metric space, and enforce physics-inspired regularization terms based on local rigidity, conservation of momentum, and isometry.
IEEE International Conference on Robotics and Automation (ICRA), 2024.
RoCo: Dialectic Multi-Robot Collaboration with Large Language Models
A novel approach to multi-robot collaboration that harnesses the power of pre-trained large language models (LLMs) for both high-level communication and low-level path planning. Robots are equipped with LLMs to discuss and collectively reason task strategies; then generate sub-task plans and task space waypoint paths, which are used by a multi-arm motion planner to accelerate trajectory planning.
CACTI: A Framework for Scalable Multi-Task Multi-Scene Visual Imitation Learning
A framework for multi-task, multi-scene robotic manipulation. It easily scales to many tasks, and uses recent advances in text2image generative models (e.g. stable-diffusion) to augment demonstration data with realistic visual variances.
Thirty-Sixth Conference on Neural Information Processing Systems (NeurIPS), 2022
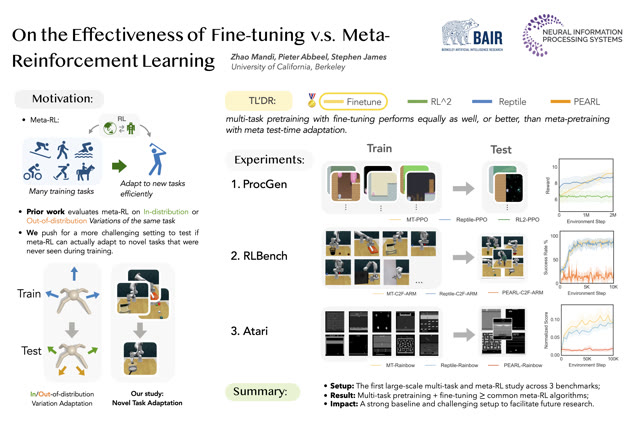
On the Effectiveness of Fine-tuning Versus Meta-reinforcement Learning
We show that multi-task pretraining with fine-tuning can perform equally as well, or better, than meta-pretraining with meta test-time adaptation. We evaluate on a novel setting using vision-based RL benchmarks, including Procgen, RLBench, and Atari, where training is done across distinct tasks, and evaluations are made on completely novel tasks.
IEEE International Conference on Robotics and Automation (ICRA), 2022.
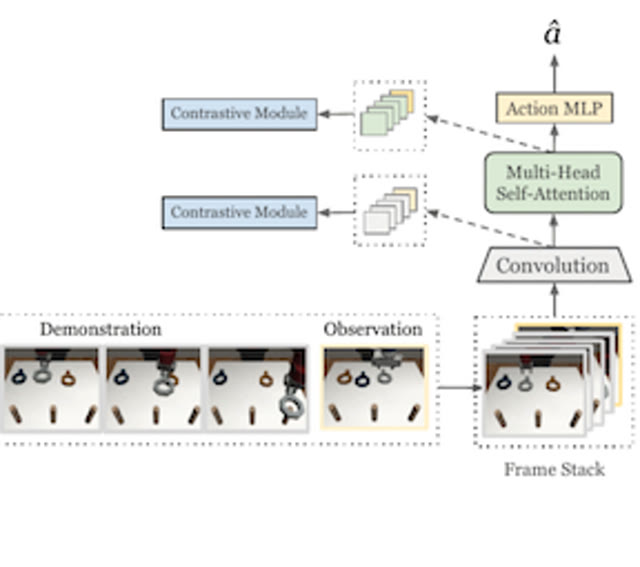
Towards More Generalizable One-shot Visual Imitation Learning
We extend one-shot imitation learning to an ambitious multi-task setup, and support this formulation by a 7-task vision-based robotic manipulation benchmark. We propose our method, MOSAIC, that tackles challenges in multi-task one-shot imitation by improving network architecture and self-supervised representation learning.